In-process guardrails for AI agents
The thing that stops a runaway agent is not a better prompt.
It is a limit. Backstop gives every agent you wrap a budget, a breaker and a concurrency cap — inside your own process, for a tenth of a millisecond, with no proxy and nothing new to run.
Prefer to look first? The dashboard runs on synthetic traffic, with no keys and no network.
01 — What actually goes wrong
Agents do not fail on one bad decision.
They fail on ten thousand good ones in a row. Three shapes, and all three have the same cause.
01
The loop that never converges
The tool errors, the agent retries, the retry errors too. The loop is not a bug in the model — it is a missing stopping condition, and it bills you every turn.
02
One agent eats everyone's budget
Ten agents share a process. One of them wants the whole window, and the other nine are fine right up until they are not.
03
The provider is down, and you are paying for the retries
Every attempt is a billed attempt. A breaker that never opens turns a provider outage into your invoice.
None of these is a model problem. All of them are a missing limit.
02 — How it works
One call, and the limits are in place.
No proxy, no sidecar, no changes to the code that calls the model. The transport is injected in-process, so requests still go straight to the provider.
Step 01
Wrap the client.
The wrapped client behaves like the one you had. Same methods, same arguments, same return value.
from openai import OpenAI
from backstop import Backstop, BackstopConfig

client = Backstop.wrap(
    OpenAI(),
    budget=50_000,     # token ceiling
    config=BackstopConfig(
        initial_concurrency=4,
    ),
)
Step 02
Set the limits.
A ceiling in tokens, a ceiling in money, a cap on requests in flight, and when to open the breaker.
client = Backstop.wrap(
    OpenAI(),
    # tokens, and dollars on top
    budget=50_000,
    budget_usd=Decimal("5.00"),
    config=BackstopConfig(
        initial_concurrency=4,  # in flight
    ),
)
Step 03
Handle the ceiling.
When the budget is reached the request never leaves your machine, and one exception is raised. It is a subclass of the provider's own error, so the handlers you already wrote still catch it.
from backstop.exceptions import BudgetExceededError

try:
    response = client.chat.completions.create(...)
except BudgetExceededError as exc:
    # A subclass of openai.OpenAIError, so the
    # handlers you already have still catch it.
    log.warning("Budget reached", extra={"used": exc.tokens_used})
Step 04
Watch it.
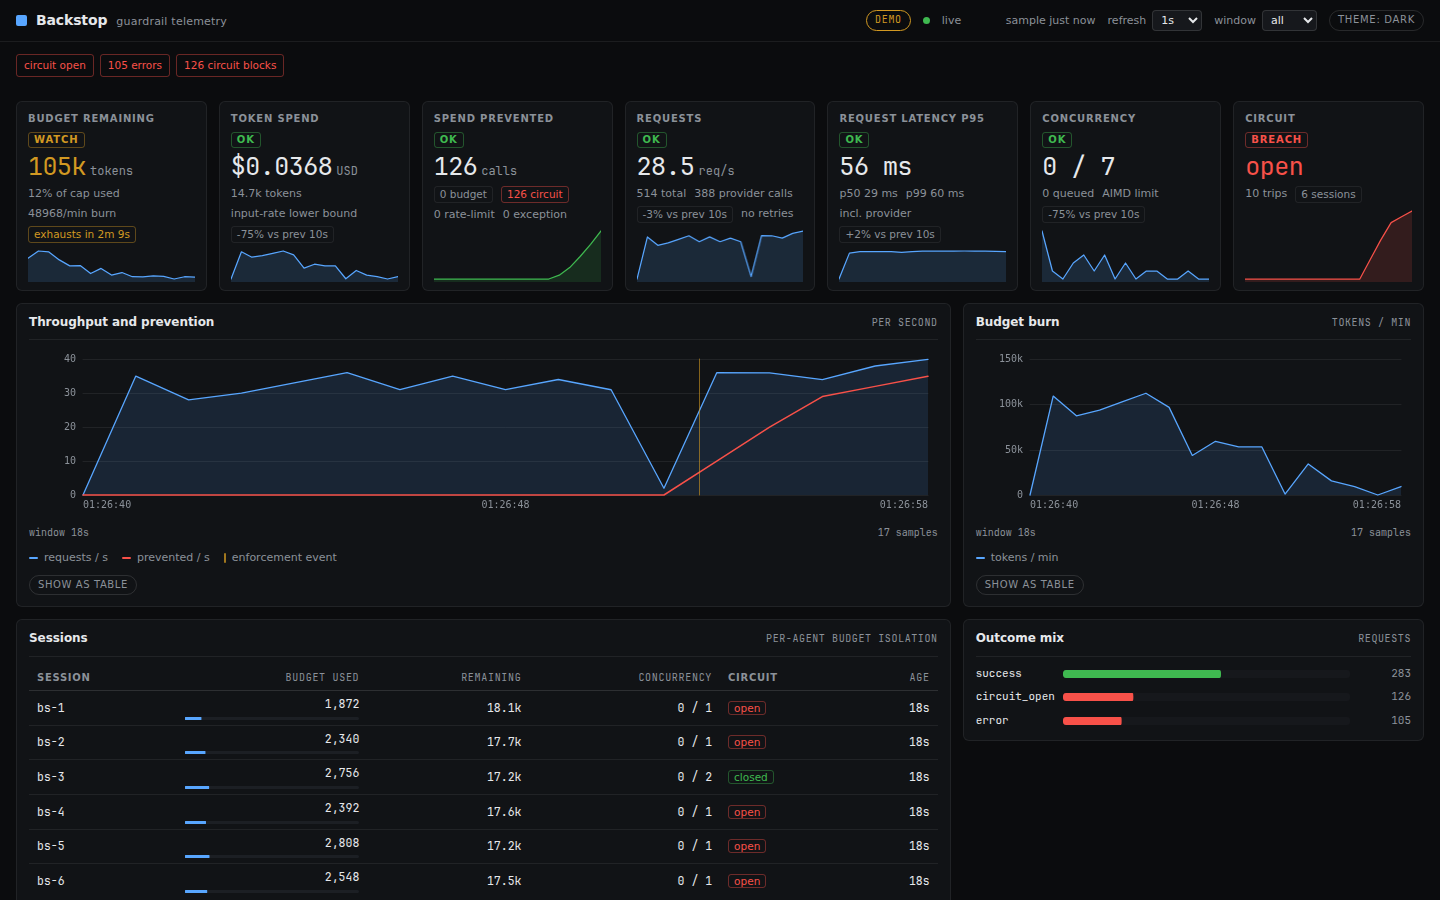
backstop dashboard opens a live view of budgets, burn rate, breaker state and every enforcement decision — with no Prometheus and no exporter. And every decision is written to a hash-chained audit log you can replay afterwards.
03 — What you get
Eight things, all of them optional.
Every one of them is a limit you can turn on, or leave off. The defaults are the boring ones.
01
Token budgets
A hard ceiling per session, per agent, or per a hierarchy of them. When it is reached, the next request never leaves your machine.
02
Dollar budgets
The same ceiling in money, priced from the model you actually call, with the arithmetic done in decimals so a cent out is a cent out.
03
Circuit breaker
When the provider starts failing, stop sending it requests. It half-opens, tries one, and closes again if the provider recovered.
04
Concurrency control
A limit on requests in flight, with a queue that prioritises instead of dropping. Critical work goes first; nothing is discarded.
05
Per-agent isolation
Each wrapped client carries its own budget. One agent cannot spend another's, and a parent can cap a whole tree of children.
06
Runaway-spend detection
Four detectors that notice a spend pattern — velocity, drift, retry amplification, context growth — before it becomes an invoice.
07
A live dashboard
Budgets, burn rate, breaker state and enforcement events, in a browser, with no Prometheus and no exporter to install.
08
An audit log
Every enforcement decision, hash-chained, so you can prove afterwards what was allowed and what was stopped.
04 — In plain words
Four hard ideas, said simply.
- Budget
- A number you promise. The agent may spend it however it likes — and when it is gone, the next request never leaves your machine. It fails in your code, where you can handle it.
- Circuit breaker
- The electrical kind. When a server keeps failing, the switch flips and stops sending it traffic for a while, then lets one request through to see if it recovered.
- Concurrency
- How many things are allowed to be in flight at once. Past that number, work waits in a queue rather than being thrown away — and a critical request waits less than a background one.
- Shadow mode
- Watch what would happen without letting it happen yet. The same budget, the same thresholds, every decision recorded — and nothing blocked.
05 — See it
The dashboard is part of the package.
Not a screenshot of a product that needs a server to go with it. A dependency-free view of the process you are already running, bound to loopback, making no outbound requests.
06 — Proof
Check it yourself, in thirty seconds, with no API key.
backstop verify runs a real wrap against a local mock transport, blocks a runaway, and prints what it measured. If it cannot prove the limits work, it says so and exits non-zero.
# Backstop Verify — 30-Second Keyless Proof

Mode: offline (local mock transport, zero network, zero keys)
Provider: openai (gpt-4o-mini simulation)

| Metric             | Result              |
|--------------------|---------------------|
| Allowed calls      | 2                   |
| Blocked calls      | 8                   |
| Tokens reserved    | 500                 |
| Tokens saved       | 2,000               |
| Exception surfaced | BudgetExceededError |
| Wall-clock overhead| 0.08 ms             |

## Mechanism Checks
- [PASS] config valid: BackstopConfig() built with sane bounds.
- [PASS] wrap pipeline: served a mock request end-to-end.
- [PASS] budget block: 8/10 runaway calls blocked at 500 tokens.
- [PASS] overhead: control-path p99 = 0.080 ms (direct 0.261 ms).
- [PASS] cache hit: the second identical request came from cache.
- [PASS] per-agent isolation: agent A blocked 5/5 at its own cap
        while agent B kept serving.

Summary: 8 passed, 0 warn, 0 failed, 0 skipped
Status: VERIFIED (real wrap enforcement active)07 — What it does not do
The things it will not do for you.
Every product has a boundary. This one draws it in public, because a guardrail you misunderstand is worse than no guardrail.
It is not a proxy
Nothing routes through Backstop. The transport is injected in-process and requests go to the provider directly, so there is no network hop to pay for and no second place to operate.
It is not a hosted control plane
There is no Backstop server, no shared policy service, and nothing to sign up for. The limits live in the process that owns the traffic.
It is not a multi-provider router
If you need to fail over between providers, use a gateway. Backstop's fallback chain stays inside one provider, on purpose.
It is not observability storage
Metrics are yours to ship. Backstop emits them and you send them where you like — there is no collector, no retention, and no query language here.
It does not enforce spend
The runaway detectors report; they never block, cancel or kill. Enforcement is the budget's job, and the budget is explicit.
The long version, with the reasoning and the trade-offs, is inthe threat model.
08 — Questions
The ones worth asking.
Does this slow my requests down?
By about a tenth of a millisecond at the median, measured on two payload sizes and published with the conditions it was measured under. The guardrail has to read and price every request, so the cost is proportional to the body.
Do I have to change my call sites?
No. You wrap the SDK client once and keep calling it the way you already do. The only other change is catching one exception type when a budget is reached — and it subclasses the provider's own error, so handlers you already have keep working.
What happens when the budget runs out?
The request is refused before it is dispatched, and a BudgetExceededError is raised. Nothing is billed, because nothing was sent. The decision is written to the audit log.
Is it Python only?
The Python package is the complete implementation. A TypeScript port of the core is in progress and is not yet a drop-in replacement — the repository says so rather than the marketing page.
Do I need Prometheus?
No. The built-in dashboard reads the process's own state and needs nothing installed beyond the standard library. Prometheus and OpenTelemetry are there if you want them, and the dashboard tells you whether they are live.
Give it one limit and see what happens.
Thirty seconds, no key, no account, no network.